Selected projects developing computational methods, datasets, and benchmarks for lexical semantic change, NLP evaluation, and computational social science.
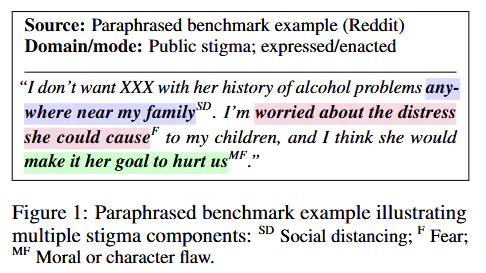
A theory-grounded, human-annotated benchmark of 470 news and social media excerpts for evaluating the detection and classification of mental health stigma in online communication.
A threshold-calibrated, prototype-based pipeline for estimating word sense prevalence in diachronic text corpora. Applied to schizophrenia in historical U.S. news, the pipeline combines sense inventories, generated prototype usages, target-aware embeddings, human-calibrated similarity thresholds, and sense prevalence estimation over time. The repository includes a sample of expert labeled U.S. news sentences (containing the term schizophrenia annotated for which Oxford English Dictionary sense they express).
Source code to evaluate key dimensions of lexical semantic change concurrently (SIB) and complementary dimensions (salience and thematic content).
Outputs LLM-generated synthetic sentences (‘Scholar-in-the-loop’ In-Context-Learning approach) to simulate dimensions of LSC.